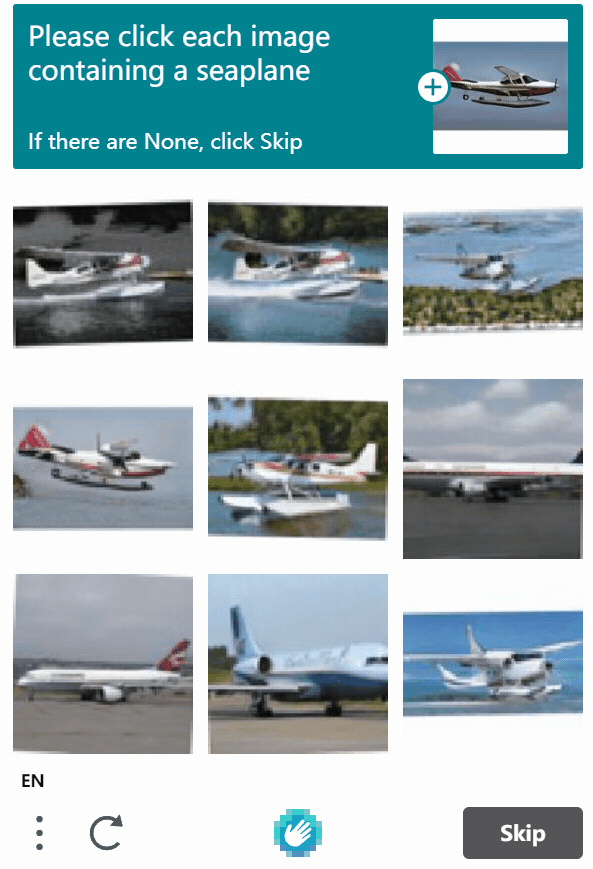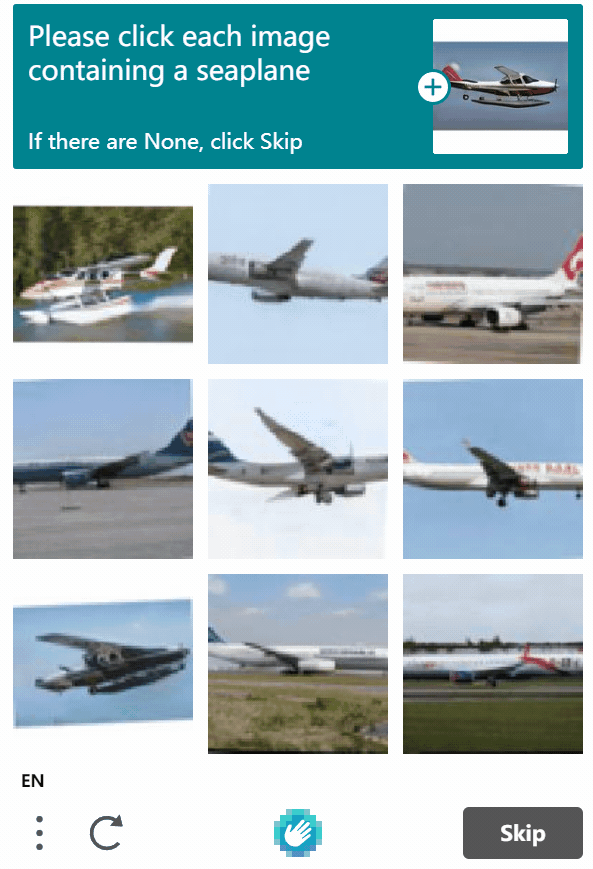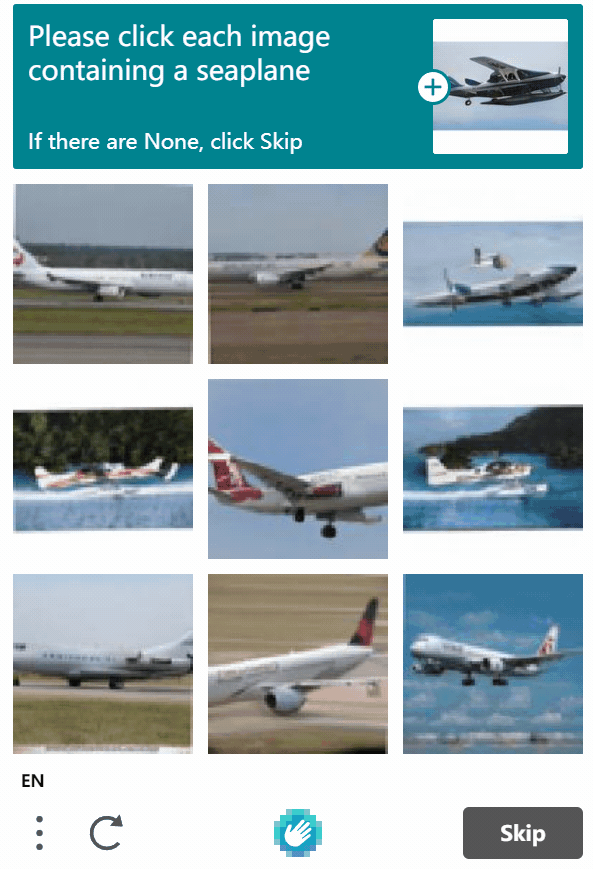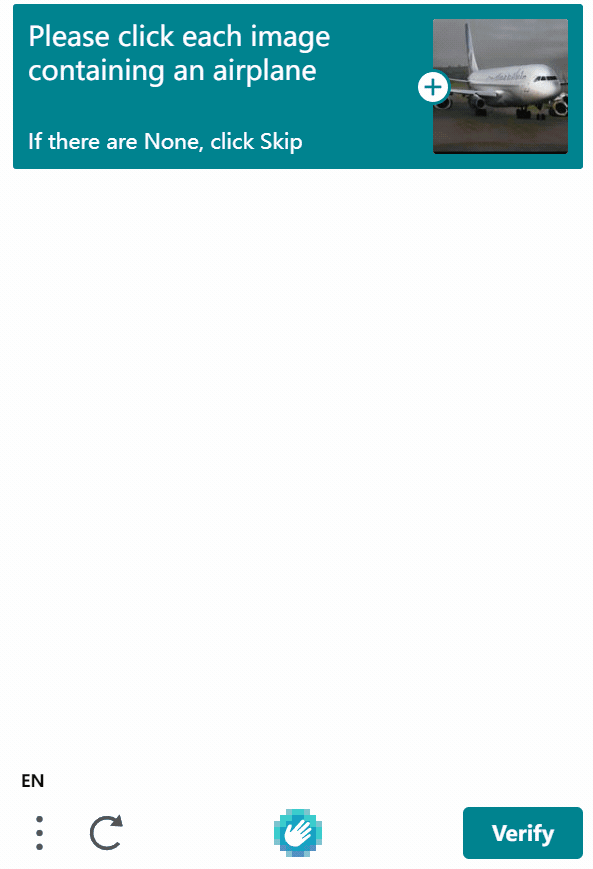
As mentioned last time, 1 seaplane, here it comes!
To be honest, there’s really not much to say, except that there are more weird creatures2… because there are too many hybrids that don’t quite fit any category. I think for the model to understand that it’s generating a seaplane, there should be a line underneath. Anyway, I feel the generative model for this task isn’t very good; the generated results are too poor.
All the code for training and testing is in this commit3. I didn’t do much generalization testing, but the results should be decent, given how much data there is.
Initially, there were many mislabeled samples in the data, which caused significant trouble for the model, leading to overfitting even when the accuracy was relatively high. Alchemy, as it were, does require some experience to find the right stopping point. Perhaps later I can write a Grid Search?
The approach this time is actually quite similar to last time, mainly because I directly built a model factory this time. This way, for any new task, I can collect some data, annotate it, train, test, and deploy—all in one go.
Actually, the solution structures for hcaptcha challengers are all quite similar, with almost no changes, except for the elephant one last time which required adding a filter. I’ll likely continue building my model factory, with little change unless the model’s generalization ability can’t keep up, such as with overly detailed images, in which case I might consider modifying the model structure.
That’s about it. Below is the demo made by @QIN2DIM